Authors: D Rawlinson and G Kowadlo
This is the first of three articles detailing our latest thinking on general intelligence: A one-size-fits-all algorithm that, like people, is able to learn how to function effectively in almost any environment. This differs from most Artificial Intelligence (AI), which is designed by people for a specific purpose. This article will set out assumptions, principles, insights and design guidelines based on what we think we already know about general intelligence. It turns out that we can describe general intelligence in some detail, although not enough detail to actually build it...yet.
The second article will look at how these ideas fit existing computational neuroscience, which helps to refine and filter the design; and the third article will describe a (high-level) algorithm that is, at least, not contradictory to the design goals and biology already established.
As usual, our plans have got ahead of implementation, so code will follow in a few weeks after the end of the series (or months...)

FIGURE 1: A hierarchy of units. Although units start out identically, they become differentiated as they learn from their unique input. The input to a unit depends on its position within the hierarchy and the state of the units connected to it. The hierarchy is conceptualized as having levels; the lowest levels are connected to sensors and motors. Higher levels are separated from sensors and motors by many intermediate units. The hierarchy may have a tree-like structure without cycles, but the number of units per level does not necessarily decrease as you move higher.
Today, those who have studied this area can talk in some detail about the nature of general intelligence without getting into specifics. Although we don’t yet have all the answers, the problem has become more approachable. For example, we’re really looking to understand a much simpler unit, not an entire brain holistically. Many complex systems can be easily understood when broken down in the right way, because we can selectively ignore detail that is irrelevant to the question at hand.
From our experience, we've developed some insights we want to share. Many of these insights were already known, and we just needed to find the right terminology. By sharing this terminology we can help others to find the right research to read.
Among other problems, we are particularly concerned about:
1. Allocation of limited resources
2: Signal dilution
3: Detached circuits within the hierarchy
4: Dilution of executive influence
5: Conflict resolution
6: Parameter selection
Let’s elaborate:
In our research we will initially adopt a fixed resource quota per hierarchy unit and a fixed branching factor for the hierarchy, allowing the structure of the hierarchy and resources per unit to be determined by data. This arrangement is the one most likely to work given a universal unit with constant parameters, as the number of inputs to each unit is constrained (due to the branching factor). It is interesting that the human cortex is a continuous sheet, and evidences dynamic resource allocation as neuroplasticity - resources can be dynamically assigned to working areas and sensors when others fail.
In any hierarchy with reciprocal connections, this problem is very likely to occur, and disastrous when it does. In Belief Propagation, another graphical model, this problem manifests as “double counting” and is avoided by nodes carefully ignoring their own evidence returned to them.

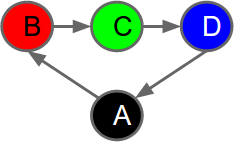
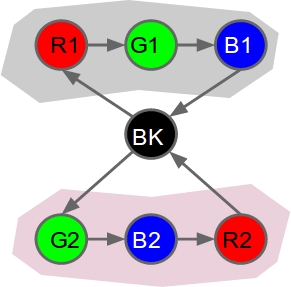
FIGURE 2: Detached circuits within the hierarchy. Units X and Y have formed a mutually reinforcing circuit that ignores all data from other parts of the hierarchy. By doing so, they have ceased to model the external world and have divided the hierarchy into separate components.
If abstract concepts exist only in higher levels of the hierarchy, they need to control large subtrees of the hierarchy over long periods of time to be successfully executed. However, if each hierarchy unit is independent; how is this control to be achieved? If higher units do not effectively subsume lower ones, executive influence will dilute as plans are incrementally re-interpreted from abstract to concrete (see figure 3). Ideally, abstract units will have quite specific control over concrete units. However, it is impractical for abstract units to have the complexity to "micro-manage" an entire tree of concrete units.

FIGURE 3: Dilution of executive influence. A high-level unit within the hierarchy wishes to execute a plan; the plan must be translated towards the most concrete units to be performed. However, each translation and re-interpretation risks losing details of the original intent which cannot be fully represented in the lower levels. Somehow, executive influence must be maintained down through an arbitrarily deep hierarchy.
Let’s define “agency” as the ability to influence or control outcomes. Lacking the ability to cause a particular outcome is a lack of agency over the desired and actual outcomes. By making each hierarchy unit responsible for the execution of goals defined in the hierarchy level immediately above, we indirectly maximise the agency of more abstract units. Without this arrangement, more abstract units would have little or no agency at all.
Figure 4 shows what happens when an abstract plan gets “lost in translation” to concrete form. I walked up to my car and pulled my keys from my pocket. The car key is on a ring with many others, but it’s much bigger and can’t be mistaken by touch. It can only be mistaken if you don’t care about the differences.
In this case, when I got to the car door I tried to unlock it with the house key! I only stopped when the key wouldn't fit in the keyhole. Strangely, all low-level mechanical actions were performed skillfully, but high level knowledge (which key) was lost. Although the plan was put in motion, it was not successful in achieving the goal.
Obviously this is just a hypothesis about why this type of error happens. What’s surprising is that it isn't more common. Can you think of any examples?
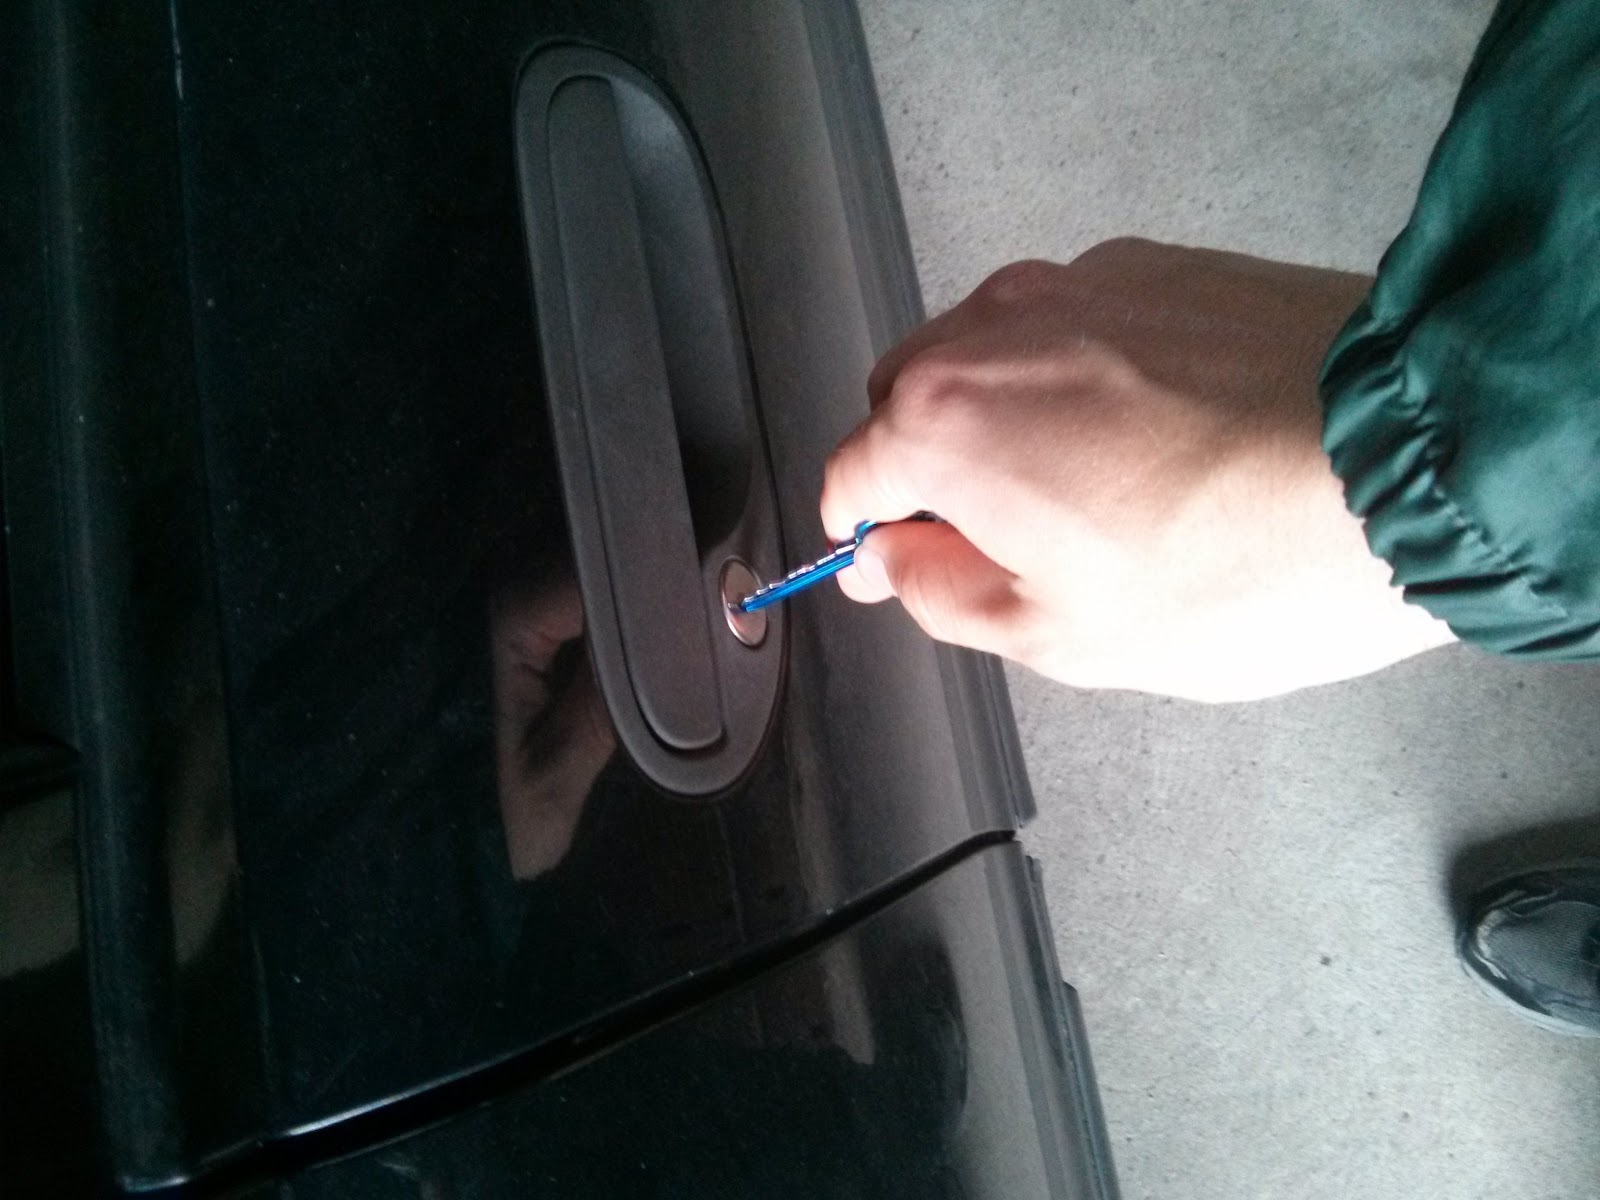 FIGURE 4: Abstract plan translation failure: Picking the wrong key but skilfully trying it in the lock. This may be an example of abstract plans being carried out, but losing relevant details while being transformed into concrete motor actions by a hierarchy of units.
In our model, planning and action selection occur as biased prediction. There is an inherent conflict between accurate prediction and bias. Attempting to bias predictions of events beyond your control leads to unexpected failure, which is even worse than expected failure.
The alternative is to predict accurately, but often the better outcome is the less likely one. There must be a mechanism to increase the probability of low-frequency events where the agent has agency over the real-world outcome.
Where possible, lower units must separate learning to predict and trying to use that learning to satisfy higher units’ objectives. Units should seek to maximise the probability of goal outcomes, given an accurate estimate of the state of the local unit as prior knowledge. But units should not become blind to objective reality in the process.
We also want the general intelligence to spontaneously create novel combinations of behaviour as a way to innovate and discover new ways to do things. Since we assume that behaviour is generated by filtering predictions, we are really saying we need to be able to predict (simulate) accurately when extrapolating combinations of existing models to new situations. So we also need conflict resolution for non-physical or non-action predictions. The agent needs a clear and decisive vision of the future, even when simulating outcomes it has never experienced.
The downside of all this creativity is that there’s really no way to tell whether these combinations are valid. Often they will be, but not always. For example, you can’t touch two objects that are far apart at the same time. When incompatible, we need a way to resolve the conflict.
There’s a good discussion of different conflict resolution strategies on Scholarpedia; our preferred technique is selecting a solitary active strategy in each hierarchy unit, choosing locally to optimise for a single objective when multiple are requested.
Evaluating alternative plans is most easily accomplished as a centralised task - you have to bring all the potential alternatives together where they can be compared. This is because we can only assign relative rewards to each alternative; it is impossible to calculate meaningful absolute rewards for the experiences of an intelligent agent. It is also important to place all plans on a level playing-field regardless of the level of abstraction; therefore abstract plans should be competing against more concrete ones and vice-versa.
Therefore, unlike most of the pieces we've described, action selection should be a centralised activity rather than a distributed one.
As a result of all these factors it will be very difficult to pick suitable values for time-constants and other parameters that control the learning processes in each unit, due to compounded uncertainty about lower units’ input. Instead, we must allow recent input to each unit to determine suitable values for parameters. This is online learning. Some parameters cannot be automatically adjusted in response to data. For these, to have any hope of debugging a general intelligence, a fixed parameter configuration must work for all units in all circumstances. This constraint will limit the use of some existing algorithms.
This is the first of three articles detailing our latest thinking on general intelligence: A one-size-fits-all algorithm that, like people, is able to learn how to function effectively in almost any environment. This differs from most Artificial Intelligence (AI), which is designed by people for a specific purpose. This article will set out assumptions, principles, insights and design guidelines based on what we think we already know about general intelligence. It turns out that we can describe general intelligence in some detail, although not enough detail to actually build it...yet.
The second article will look at how these ideas fit existing computational neuroscience, which helps to refine and filter the design; and the third article will describe a (high-level) algorithm that is, at least, not contradictory to the design goals and biology already established.
As usual, our plans have got ahead of implementation, so code will follow in a few weeks after the end of the series (or months...)

FIGURE 1: A hierarchy of units. Although units start out identically, they become differentiated as they learn from their unique input. The input to a unit depends on its position within the hierarchy and the state of the units connected to it. The hierarchy is conceptualized as having levels; the lowest levels are connected to sensors and motors. Higher levels are separated from sensors and motors by many intermediate units. The hierarchy may have a tree-like structure without cycles, but the number of units per level does not necessarily decrease as you move higher.
Architecture of General Intelligence
Let’s start with some fundamental assumptions and outline the structure of a system that has general intelligence characteristics.It Exists
We assume there exists a “general intelligence algorithm” that is not irreducibly complex. That is, we don’t need to understand it in excruciating detail. Instead, we can break it down into simpler models that we can easily understand in isolation. This is not necessarily a reasonable assumption, but there is evidence for it:Units
A general intelligence algorithm can be described more simply as a collection of many simpler, functionally-identical units. Again, this is a big assumption, but it is supported by at least two pieces of evidence. First, it has often been observed that the human cortex has quite uniform structure across areas having greatly varying functional roles. Second, this structure has revealed that the cortex is made up of many smaller units (called columns, at one particular scale). It is reasonable to decompose the cortex in this way due to high and varied intra-column connectivity and limited variety of inter-column connectivity. The patterns of inter and intra column connectivity are very similar throughout the cortex. “Columns” contain only a few thousand neurons organized into layers and micro-columns that further simplify understanding of the structure. That’s not overwhelmingly complex, although we are making simplifying assumptions about neuron function.Hierarchy
Our reading and experimentation has suggested that hierarchical representation is critical for the types of information processing involved in general intelligence. Hierarchies are built from many units connected together in layers. Typically, only the lowest level of the hierarchy receives external input. Other levels receive input from lower levels of the hierarchy instead. For more background on hierarchies, see earlier posts. Hierarchy allows units in higher layers to model more complex and abstract features of input, despite the fixed complexity of each unit. Hierarchy also allows units to cover all available input data and allow combinations of features to be jointly represented within a reasonable memory limit. It’s a crucial concept.Synchronization
Do we need synchronization between units? Synchronization can simplify sequence modelling in a hierarchy by restricting the number of possible permutations of events. However, synchronization between units may significantly hinder fast execution on parallel computing hardware, so this question is important. A point of confusion may be the difference between synchronization and timing / clock signals. We can have synchronization without clocks, but in any case there is biological evidence of timing signals within the brain. Pathological conditions can arise without a sense of time. In conclusion we’re going to assume that units should be functionally asynchronous, but might make use of clock signals.Robustness
Your brain doesn’t completely stop working if you damage it. Robustness is a characteristic of a distributed system and one we should hope to emulate. Robustness applies not just to internal damage but external changes (i.e. it doesn't matter if your brain is wrong or the world has changed; either way you have to learn to cope).Scalability
Adding more units should improve capability and performance. The algorithm must scale effectively without changes other than having more of the same units appended to the hierarchy. Note the specific criteria for how scalability is to be achieved (i.e. enlarge the hierarchy rather than enlarge the units). It is important to test for this feature to demonstrate the generality of the solution.Generality
The same unit should work reasonably well for all types of input data, without preprocessing. Of course, tailored preprocessing could make it better, but it shouldn’t be essential.Local interpretation
The unit must locally interpret all input. In real brains it isn’t plausible that neuron X evolved to target neuron Y precisely. Neurons develop dendrites and synapses with sources and targets that are carefully guided, but not to the extent of identifying specific cells amongst thousands of peers. Any algorithm that requires exact targeting or mapping of long-range connections is biologically implausible. Rather, units should locally select and interpret incoming signals using characteristics of the input. Since many AI methods require exact mapping between algorithm stages, this principle is actually quite discriminating.Cellular plausibility
Similarly, we can validate designs by questioning whether they could develop by biologically plausible processes, such as cell migration or preferential affinity for specific signal coding or molecular markers. However, be aware that brain neurons rarely match the traditional integrate-and-fire model.Key Insights
It’s surprising that in careers cumulatively spanning more than 25 years we (the authors) had very little idea how the methods we used everyday could lead to general intelligence. It is only in the last 5 years that we have begun to research the particular sub-disciplines of AI that may lead us in that direction.Today, those who have studied this area can talk in some detail about the nature of general intelligence without getting into specifics. Although we don’t yet have all the answers, the problem has become more approachable. For example, we’re really looking to understand a much simpler unit, not an entire brain holistically. Many complex systems can be easily understood when broken down in the right way, because we can selectively ignore detail that is irrelevant to the question at hand.
From our experience, we've developed some insights we want to share. Many of these insights were already known, and we just needed to find the right terminology. By sharing this terminology we can help others to find the right research to read.
We’re looking for a stackable building block, not the perfect monolith
We must find a unit that can be assembled into an arbitrarily large - yet still functional - structure. In fact, a similar feature was instrumental in the success of “deep” learning: Networks could suddenly be built up to arbitrary depths. Building a stackable block is surprisingly hard and astonishingly important.We’re not looking to beat any specific benchmark
... but if we could do reasonably well at a wide range of benchmarks, that would be exciting. This is why the DeepMind Atari demos are so exciting; the same algorithm could succeed in very different problems.Abstraction by accumulation of invariances
This insight comes from Hawkins’ work on Hierarchical Temporal Memory. He proposes that abstraction towards symbolic representation comes about incrementally, rather than as a single mapping process. Concepts accumulate invariances - such as appearance from different angles - until labels can correctly be associated with them. This neatly avoids the fearful “symbol grounding problem” from the early days of AI.Biased Prediction and Selective Attention are both action selection
We believe that selective bias of predictions and expectations is responsible for both narrowing of the range of anticipated futures (selective ignorance of potential outcomes) and the mechanism by which motor actions are generated. A selective prediction of oneself performing an action is a great way to generate or “select” that action. Similarly, selective attention to external events affects the way data is perceived and in turn the way the agent will respond. Filtering data flow between hierarchy units implements both selective attention and action selection, if data flowing towards motors represents candidate futures including both self-actions and external consequences.The importance of spatial structure in data
As you will see in later parts of this article series, the spatial structure of input data is actually quite important when training our latest algorithms. This is not true of many algorithms, especially in Machine Learning where each input scalar is often treated as an independent dimension. Note that we now believe spatial structure is important both in raw input and in data communicated between units. We’re not simply saying that external data structure is important to the algorithm - we’re claiming that simulated spatial structure is actually an essential part of algorithms for dynamically dividing a pool of resources between hierarchy units.Binary data
There's a lot of simplification and assumption here, but we believe this is the most useful format for input and internal data. In any case, the algorithms we’re finding most useful can't easily be refactored for the obvious alternative (continuous input values). However, continuous input can be encoded with some loss of precision as subsets of bits. There is some evidence that this is biologically plausible, but it is not definitive. Why binary? Dimensionality reduction is an essential feature of a hierarchical model; it may be that sparse binary representations are simply a good compromise between data loss and qualities such as compositionality:Sparse, Distributed Representations
We will be using Sparse, Distributed Representations (SDRs) to represent agent and world state [RE ]. SDRs are binary data (i.e. all values are 1 or 0). SDRs are sparse, meaning that at any moment, only a fraction of the bits are 1's (active). The most complex feature to grasp is that SDRs are distributed: No individual bit uniquely represents anything. Instead, data features are jointly represented by sets of bits. SDRs are overcomplete representations - not all bits in a feature-set are required to “detect” a feature, which also means that degrees of similarity can also be expressed as if the data were continuous. These characteristics also mean that SDRs are robust to noise - missing bits are unlikely to affect interpretation. .Predictive Coding
SDRs are a specific form of Sparse (Population) Coding where state is jointly represented by a set of active bits. Transforming data into a sparse representation is necessarily lossy and balances representational capacity against bit-density. The most promising sparse coding scheme we have identified is Predictive Coding, in which internal state is represented by prediction errors. PC has the benefit that errors are propagated rather than hidden in local states, and data dimensionality automatically reduces in proportion to its predictability. Perfect prediction implies that data is fully understood, and produces no output. A specific description of PC is given by Friston et al but a more general framework has been discussed in several papers by Rao, Ballard et al since about 1999. The latter is quite similar to the inter-region coding via temporal pooling described in the HTM Cortical Learning Algorithm.Generative Models
Training an SDR typically produces a Generative Model of its input. This means that the system encodes observed data in such a way that it can generate novel instances of observed data. In other words, the system can generate predictions of all inputs (with varying uncertainty) from an arbitrary internal state. This is a key prerequisite for a general intelligence that must simulate outcomes for planned novel action combinations.Dimensionality Reduction
In constructing models, we will be looking to extract stable features and in doing so reduce the complexity of input data. This is known as dimensionality reduction, for which we can use algorithms such as auto-encoders. To cope with the vast number of possible permutations and combinations of input, an incredibly efficient incremental process of compression is required. So how can we detect stable features within data?
Unsupervised Learning
By the definition of general intelligence, we can’t possibly hope to provide a tutor-algorithm that provides the optimum model update for every input presented. It’s also worth noting that internal representations of the world and agent should be formed without consideration of the utility of the representations - in other words, internal models should be formed for completeness, generality and accuracy rather than task-fulfilment. This allows less abstract representations to become part of more abstract, long-term plans, despite lacking immediate value. It requires that we use unsupervised learning to build internal representations.Hierarchical Planning & Execution
We don’t want to have to model the world twice: Once for understanding what’s happening, and again for planning & control. The same model should be used for both. This means we have to do planning & action selection within the single hierarchical model used for perception. It also makes sense, given that the agent’s own actions will help to explain sensor input (for example, turning your head will alter the images received in a predictable way). As explained earlier, we can generate plans by simply biasing “predictions” of our own behaviour towards actions with rewarding outcomes.Reinforcement Learning
In the context of an intelligent agent, it is generally impossible to discover the “correct” set of actions or output for any given situation. There are many alternatives of varying quality; we don’t even insist on the best action but expect the agent to usually pick rewarding actions. In these scenarios, we will require a Reinforcement Learning system to model the quality of the actions considered by the agent. Since there is value in exploration, we may also expect the agent to occasionally pick suboptimal strategies, to learn new information.Supervised Learning
There is still a role for supervised learning within general intelligence. Specifically, during the execution of hierarchical control tasks we can describe both the ideal outcome and some metric describing similarity of actual outcome to desired. Supervised learning is ideal for discovery of actions with agency to bring about desired results. Supervised Learning can tell us how best to execute a plan constructed in an Unsupervised Learning model, that was later selected by Reinforcement Learning.Challenges Anticipated
The features and constraints already identified mean that we can expect some specific difficulties when creating our general intelligence.Among other problems, we are particularly concerned about:
1. Allocation of limited resources
2: Signal dilution
3: Detached circuits within the hierarchy
4: Dilution of executive influence
5: Conflict resolution
6: Parameter selection
Let’s elaborate:
Allocation of limited resources
This is an inherent problem when allocating a fixed pool of computational resources (such as memory) to a hierarchy of units. Often, resources per unit are fixed, ensuring that there are sufficient resources for the desired hierarchy structure. However, this is far less efficient than dynamically allocating resources to units to globally maximize performance. It also presupposes the ideal hierarchy structure is known, and not a function of the data. If the hierarchy structure is also dynamic, this becomes particularly difficult to manage because resources are being allocated at two scales simultaneously (resources → units and units → hierarchy structure), with constraints at both scales.In our research we will initially adopt a fixed resource quota per hierarchy unit and a fixed branching factor for the hierarchy, allowing the structure of the hierarchy and resources per unit to be determined by data. This arrangement is the one most likely to work given a universal unit with constant parameters, as the number of inputs to each unit is constrained (due to the branching factor). It is interesting that the human cortex is a continuous sheet, and evidences dynamic resource allocation as neuroplasticity - resources can be dynamically assigned to working areas and sensors when others fail.
Signal Dilution
As data is transformed from raw input into a hierarchical model, information will be lost (not represented anywhere). This problem is certain to occur in all realistic tasks because input data will be modelled locally in each unit without global oversight over which data is useful. Given local resource constraints, this will be a lossy process. Moreover, we have also identified the need for units to identify patterns in the data and output a simplified signal for higher-order modelling by other units in the hierarchy (dimensionality reduction). Therefore, each unit will deliberately and necessarily lose data during these transformations. We will use techniques such as Predictive Coding to allow data that is not understood (i.e. not predictable) to flow through the system until it can be modelled accurately (predicted). However, it will still be important to characterise the failure modes in which important data is eliminated before it can be combined with other data that provides explanatory power.Detached circuits within the hierarchy
Consider figure 2. Here we have a tree of hierarchy units. If the interactions between units are reciprocal (i.e. X outputs to Y and receives data from Y) there is a strong danger of small self-reinforcing circuits forming in the hierarchy. These feedback circuits exchange mutually complementary data between a pair or more units, causing them to ignore data from the rest of the hierarchy. In effect, the circuit becomes “detached” from the rest of the hierarchy. Since sensor data enters via leaf-units at the bottom of the hierarchy, everything above the detached circuit is also detached from the outside world and the system will cease to function satisfactorily.In any hierarchy with reciprocal connections, this problem is very likely to occur, and disastrous when it does. In Belief Propagation, another graphical model, this problem manifests as “double counting” and is avoided by nodes carefully ignoring their own evidence returned to them.

FIGURE 2: Detached circuits within the hierarchy. Units X and Y have formed a mutually reinforcing circuit that ignores all data from other parts of the hierarchy. By doing so, they have ceased to model the external world and have divided the hierarchy into separate components.
Dilution of executive influence
A generally-intelligent agent needs to have the ability to execute abstract, high-level plans as easily as primitive, immediate actions. As people we often conceive plans that may take minutes, hours, days or even longer to complete. How is execution of lengthy plans achieved in a hierarchical system?If abstract concepts exist only in higher levels of the hierarchy, they need to control large subtrees of the hierarchy over long periods of time to be successfully executed. However, if each hierarchy unit is independent; how is this control to be achieved? If higher units do not effectively subsume lower ones, executive influence will dilute as plans are incrementally re-interpreted from abstract to concrete (see figure 3). Ideally, abstract units will have quite specific control over concrete units. However, it is impractical for abstract units to have the complexity to "micro-manage" an entire tree of concrete units.

FIGURE 3: Dilution of executive influence. A high-level unit within the hierarchy wishes to execute a plan; the plan must be translated towards the most concrete units to be performed. However, each translation and re-interpretation risks losing details of the original intent which cannot be fully represented in the lower levels. Somehow, executive influence must be maintained down through an arbitrarily deep hierarchy.
Let’s define “agency” as the ability to influence or control outcomes. Lacking the ability to cause a particular outcome is a lack of agency over the desired and actual outcomes. By making each hierarchy unit responsible for the execution of goals defined in the hierarchy level immediately above, we indirectly maximise the agency of more abstract units. Without this arrangement, more abstract units would have little or no agency at all.
Figure 4 shows what happens when an abstract plan gets “lost in translation” to concrete form. I walked up to my car and pulled my keys from my pocket. The car key is on a ring with many others, but it’s much bigger and can’t be mistaken by touch. It can only be mistaken if you don’t care about the differences.
In this case, when I got to the car door I tried to unlock it with the house key! I only stopped when the key wouldn't fit in the keyhole. Strangely, all low-level mechanical actions were performed skillfully, but high level knowledge (which key) was lost. Although the plan was put in motion, it was not successful in achieving the goal.
Obviously this is just a hypothesis about why this type of error happens. What’s surprising is that it isn't more common. Can you think of any examples?
In our model, planning and action selection occur as biased prediction. There is an inherent conflict between accurate prediction and bias. Attempting to bias predictions of events beyond your control leads to unexpected failure, which is even worse than expected failure.
The alternative is to predict accurately, but often the better outcome is the less likely one. There must be a mechanism to increase the probability of low-frequency events where the agent has agency over the real-world outcome.
Where possible, lower units must separate learning to predict and trying to use that learning to satisfy higher units’ objectives. Units should seek to maximise the probability of goal outcomes, given an accurate estimate of the state of the local unit as prior knowledge. But units should not become blind to objective reality in the process.
Conflict resolution
General intelligence must be able to function effectively in novel situations. Modelling and prediction must work in the first instance, without time for re-learning. This means that existing knowledge must be combined effectively to extrapolate to a novel situation.We also want the general intelligence to spontaneously create novel combinations of behaviour as a way to innovate and discover new ways to do things. Since we assume that behaviour is generated by filtering predictions, we are really saying we need to be able to predict (simulate) accurately when extrapolating combinations of existing models to new situations. So we also need conflict resolution for non-physical or non-action predictions. The agent needs a clear and decisive vision of the future, even when simulating outcomes it has never experienced.
The downside of all this creativity is that there’s really no way to tell whether these combinations are valid. Often they will be, but not always. For example, you can’t touch two objects that are far apart at the same time. When incompatible, we need a way to resolve the conflict.
There’s a good discussion of different conflict resolution strategies on Scholarpedia; our preferred technique is selecting a solitary active strategy in each hierarchy unit, choosing locally to optimise for a single objective when multiple are requested.
Evaluating alternative plans is most easily accomplished as a centralised task - you have to bring all the potential alternatives together where they can be compared. This is because we can only assign relative rewards to each alternative; it is impossible to calculate meaningful absolute rewards for the experiences of an intelligent agent. It is also important to place all plans on a level playing-field regardless of the level of abstraction; therefore abstract plans should be competing against more concrete ones and vice-versa.
Therefore, unlike most of the pieces we've described, action selection should be a centralised activity rather than a distributed one.
Parameter Selection
In a hierarchical system the input to “higher” units will be determined by modelling in “lower” units and interactions with the world. The agent-world system will develop in markedly different ways each time. It will take an unknown amount of time for stable modelling to emerge, first in the lower units and then moving higher in the hierarchy.As a result of all these factors it will be very difficult to pick suitable values for time-constants and other parameters that control the learning processes in each unit, due to compounded uncertainty about lower units’ input. Instead, we must allow recent input to each unit to determine suitable values for parameters. This is online learning. Some parameters cannot be automatically adjusted in response to data. For these, to have any hope of debugging a general intelligence, a fixed parameter configuration must work for all units in all circumstances. This constraint will limit the use of some existing algorithms.